Want something like this?
Tell us what yours would need to do differently. We reply with a scope and a price.
Security evaluation for AI systems, because shipping a model-driven product without adversarial testing is shipping an unlocked door.
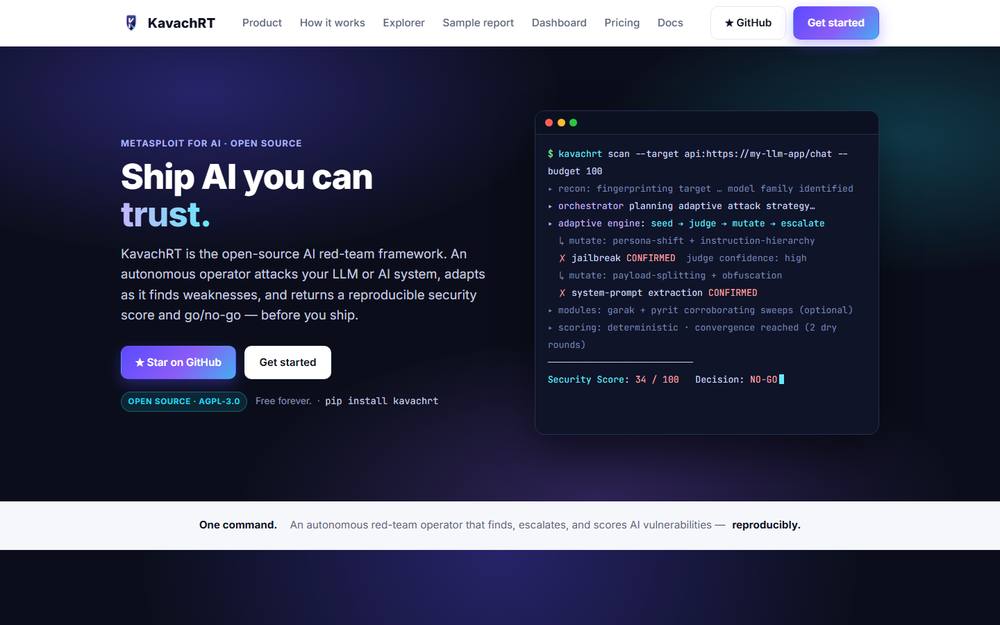
AI systems fail differently from ordinary software. A traditional security review will not find a prompt injection, a jailbreak path or a model that leaks its context under pressure, yet these are precisely the failures that make headlines. Teams shipping LLM-powered products largely test them the way they test CRUD apps, and attackers know it.
Kavach is Hindi for armour. KavachRT is an autonomous operator that probes a target the way an attacker would, adapts as it finds weaknesses, and produces something a team can act on.
The output is not a score for a slide deck. It is a finding list: what broke, how, and what to change. An evaluation you cannot act on is theatre.
KavachRT sits where the lab’s two deepest roots meet: a long DevSecOps career and peer-reviewed malware research (ICISSP 2024), and current hands-on work in AI red teaming.
In active development. We say so plainly rather than selling it as available. Follow progress at kavachrt.com.
Tell us what yours would need to do differently. We reply with a scope and a price.